I am a master’s student at Beihang University, supervised by Prof. Si Liu. Before that, I received my bachelor’s degree in Software Engineering from Beihang University.

My research interests include Agentic AI, MLLMs, AIGC, and Embodied AI. Welcome for discussion and collaboration, feel free to drop me an email.

✉️ I’ll be on the job market in 2027. Happy to connect about opportunities!

🔥 News

  • 2026.10: 🔥 Release OneSearch-VL, a unified multimodal deep research agent for images and videos.
  • 2026.09: 🎉 Gen-Searcher is accepted to NeurIPS 2026.
  • 2026.08: 🎉 OmniAlpha is accepted to ACM MM 2026 as an Oral presentation.
  • 2026.08: 🎉 Video-MME-Logical is accepted to Findings of EMNLP 2026.
  • 2026.06: 🔥 Release Video-MME-Logical, using visual coding to generate controllable videos at scale for training and benchmarking.
  • 2026.06: 🎉 OpenSubject is accepted to ECCV 2026.
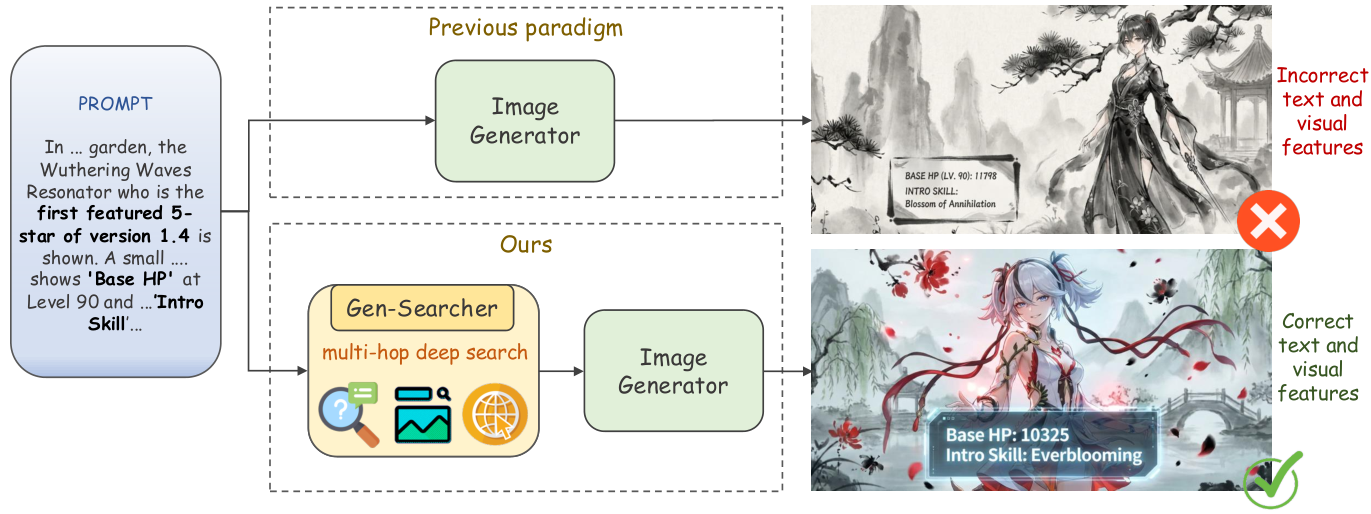
  • 2026.03: 🔥 Release Gen-Searcher, a deep research agent that searches for knowledge and reference images to guide image generation.
  • 2026.02: 🎉 Four papers are accepted to CVPR 2026 (3 Main, 1 Findings).
  • 2026.01: 🎉 AerialVLA is accepted to AAAI 2026.
  • 2025.12: 🔥 Release EditThinker, unlocking iterative reasoning for image editors.
  • 2025.12: 🔥 Release OneThinker, an all-in-one reasoning model for image and video understanding.
  • 2025.11: 🔥 Release Thinking-While-Generating, interleaving textual reasoning throughout visual generation!
  • 2025.09: 🎉 Temporal-R1 is accepted to the NeurIPS@NextVid 2025 as an Oral presentation.
  • 2025.07: 🔥 Release LLaVA-ST, with code, models, and ST-Align data and benchmarks for fine-grained spatial-temporal understanding.
  • 2025.02: 🎉 LLaVA-ST and VCT are accepted to CVPR 2025.
  • 2025.01: 🎉 Point Cluster is accepted to ICLR 2025, and AL-Ref-SAM2 is accepted to AAAI 2025.
  • 2024.07: 🎉 Dynamic Prompting is accepted to ACM MM 2024.

📝 Publications

* Equal contribution · † Project lead · ‡ Corresponding author. Full list on Google Scholar.

Agentic AI

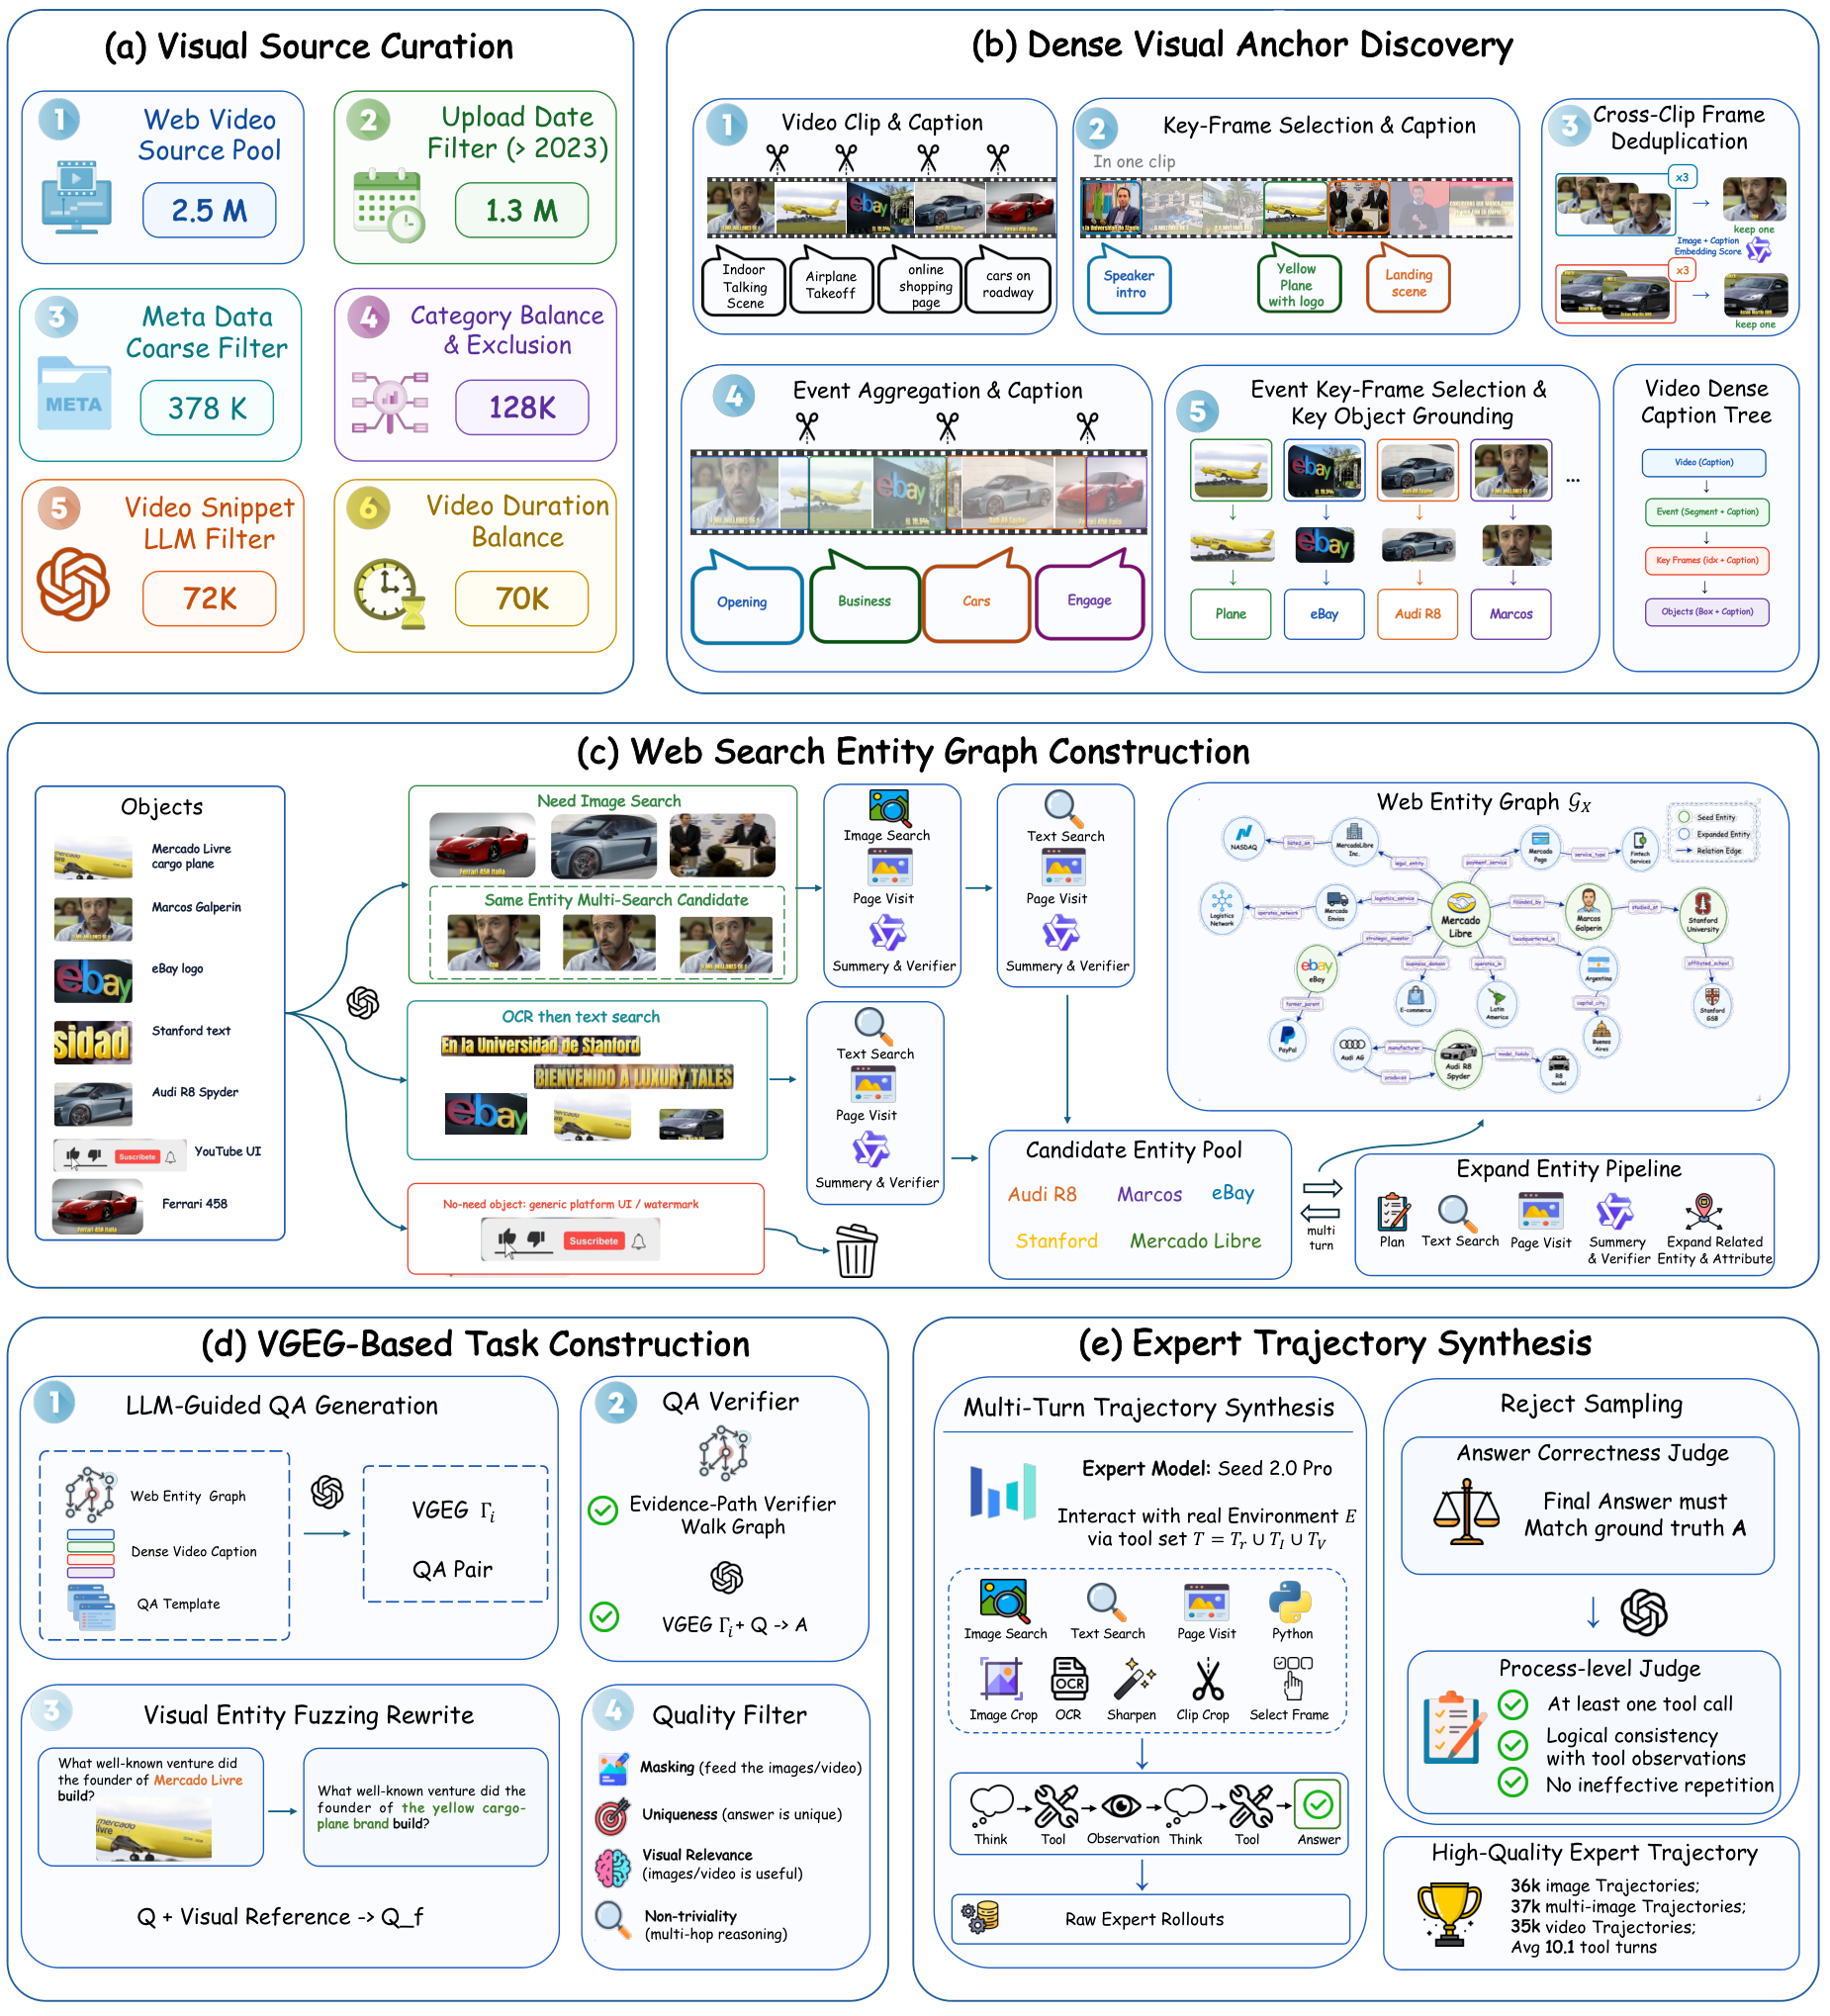
Tech Report OneSearch-VL: Unified Multimodal Deep Research Agent for Image and Video

Hongyu Li, Manyuan Zhang†, Kaituo Feng, Shu Chen, Dian Zheng, Hao Li, Hao Yu, Zhangquan Chen, Zoey Guo, Ray Zhang, Shaofei Huang, Tianrui Hui, Linjiang Huang, Si Liu‡.

Unifies single-image, multi-image, and video deep research in one agent.
[PDF] [Code]
Show FigureHide Figure: OneSearch-VL: Unified Multimodal Deep Research Agent for Image and Video
Overview of OneSearch-VL: Unified Multimodal Deep Research Agent for Image and Video
OneSearch-VL: Unified Multimodal Deep Research Agent for Image and Video

NeurIPS 2026 Gen-Searcher: Reinforcing Agentic Search for Image Generation

Kaituo Feng, Manyuan Zhang, Shuang Chen, Yunlong Lin, Kaixuan Fan, Yilei Jiang, Hongyu Li, Dian Zheng, Chenyang Wang, Xiangyu Yue.

First work to explore training a deep research agent for generation.
[PDF] [Code] [Project]
Show FigureHide Figure: Gen-Searcher: Reinforcing Agentic Search for Image Generation
Overview of Gen-Searcher: Reinforcing Agentic Search for Image Generation
Gen-Searcher: Reinforcing Agentic Search for Image Generation

arXiv 2025 EditThinker: Unlocking Iterative Reasoning for Any Image Editor

Hongyu Li, Manyuan Zhang†, Dian Zheng, Ziyu Guo, Yimeng Jia, Kaituo Feng, Hao Yu, Yexin Liu, Yan Feng, Peng Pei, Xunliang Cai, Linjiang Huang, Hongsheng Li, Si Liu‡.

Enables MLLMs to use image generators as tools for agentic iterative reasoning and self-refinement of generated results.
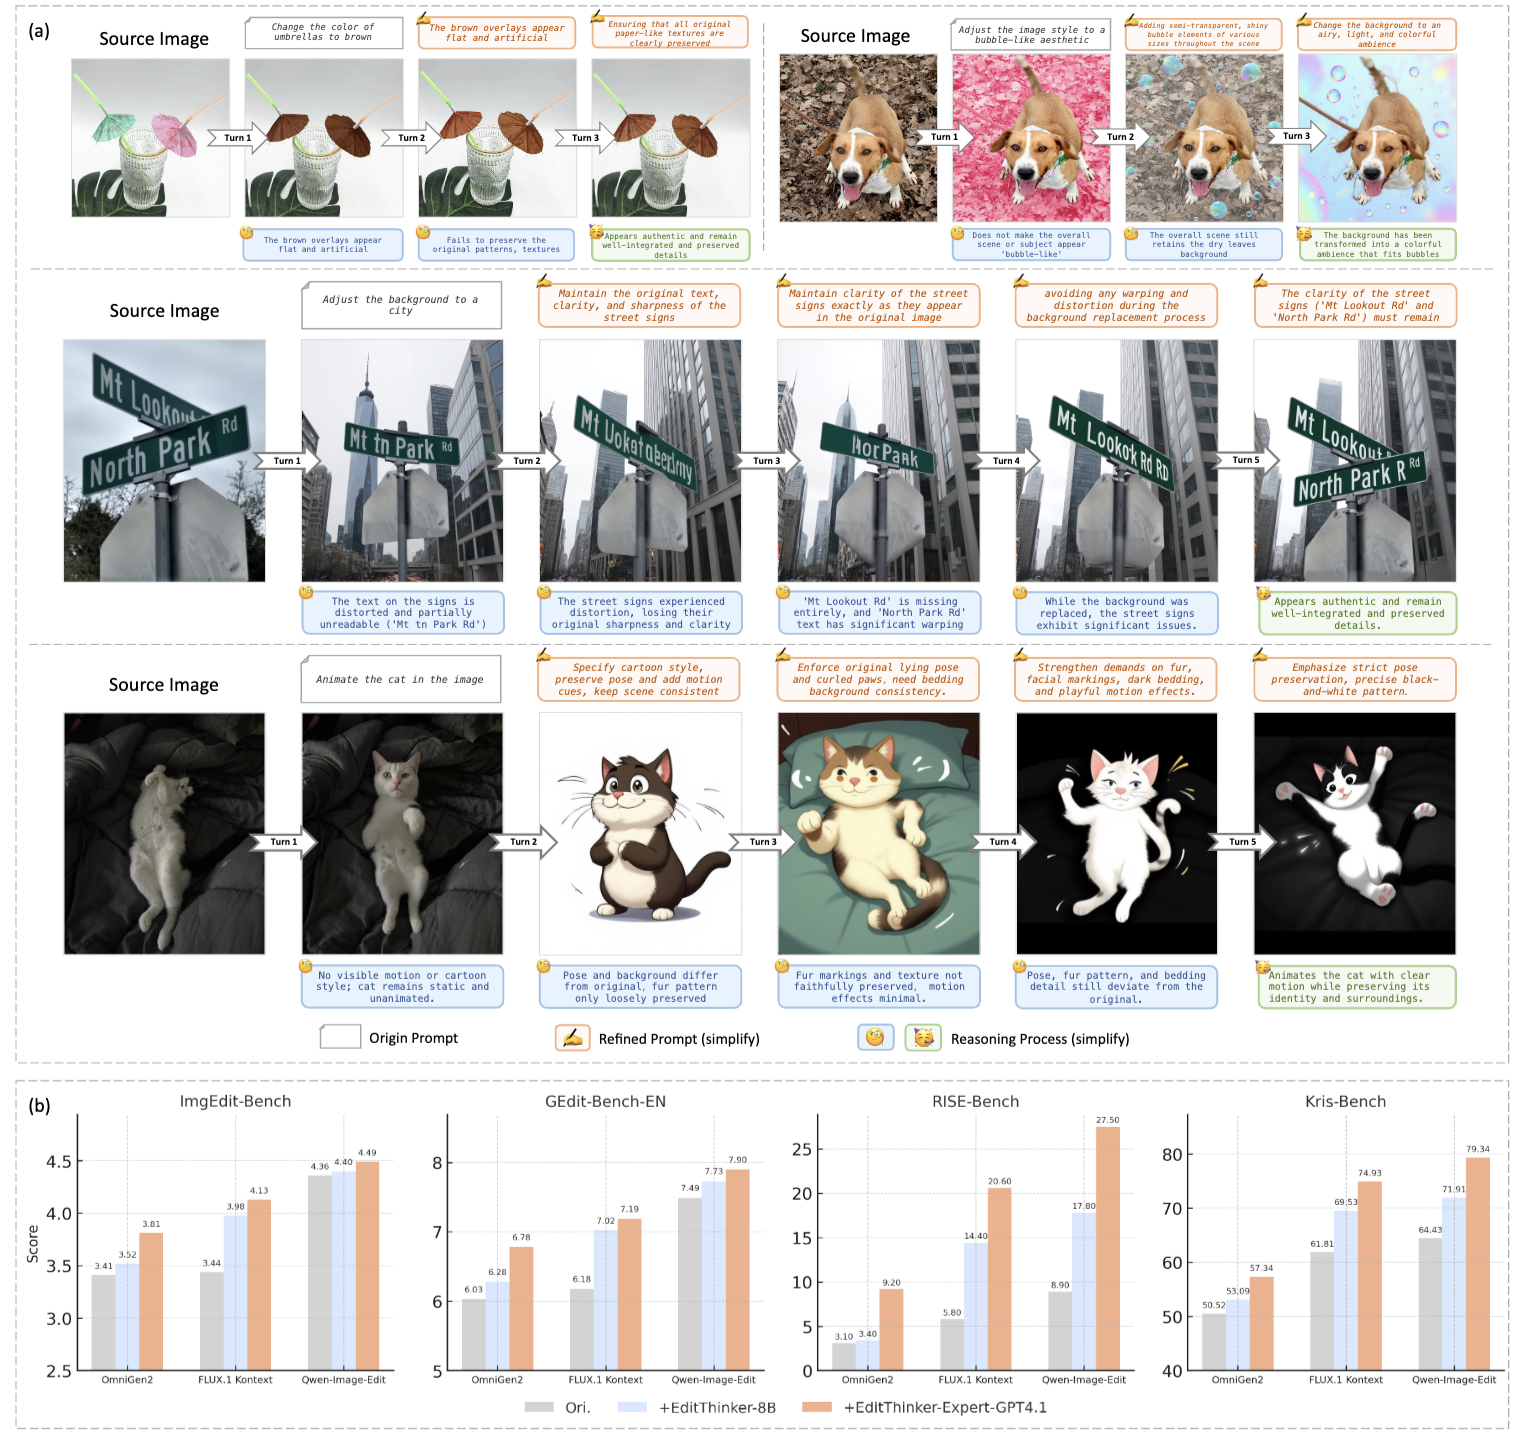
[PDF] [Code] [Project]
Show FigureHide Figure: EditThinker: Unlocking Iterative Reasoning for Any Image Editor
Overview of EditThinker: Unlocking Iterative Reasoning for Any Image Editor
EditThinker: Unlocking Iterative Reasoning for Any Image Editor

Multimodal Understanding & Reasoning

EMNLP 2026 Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning

Hohin Kwan*, Hongyu Li*†, Ray Zhang, Manyuan Zhang, Xianghao Kong, Anyi Rao, Jiahao Xie‡, Si Liu.

Uses visual coding to generate controllable videos at scale for training and benchmarking.
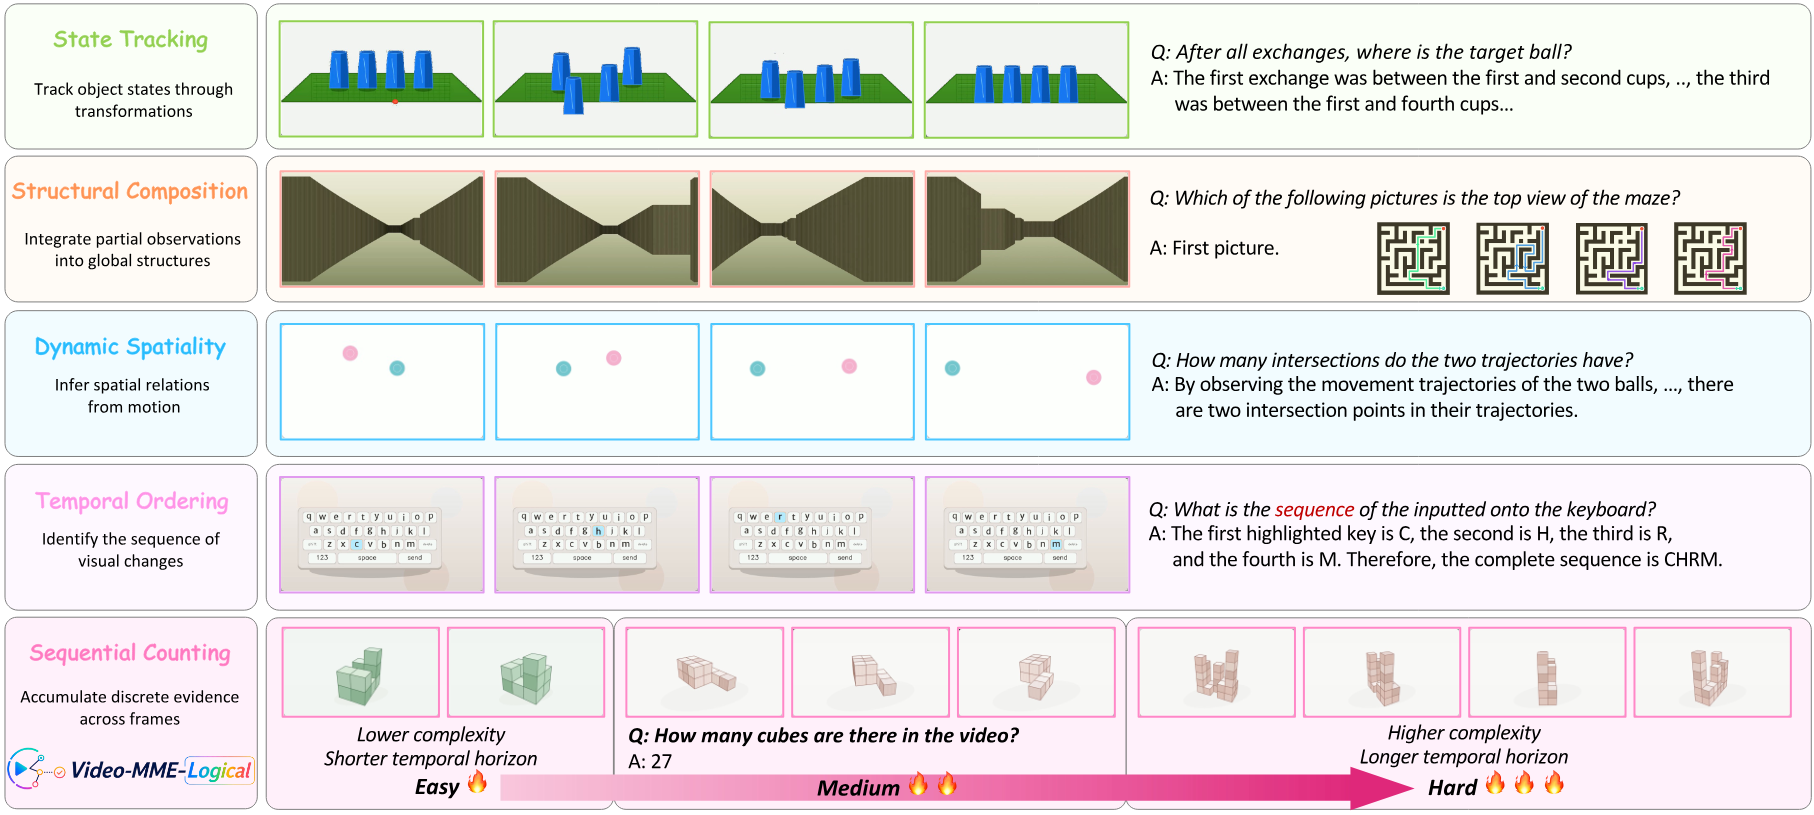
[PDF] [Code] [Project]
Show FigureHide Figure: Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning
Overview of Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning
Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning

NeurIPS@NextVid 2025 Oral Reinforcement Learning Tuning for VideoLLMs: Reward Design and Data Efficiency

Hongyu Li*, Songhao Han*, Yue Liao*†, Junfeng Luo, Jialin Gao, Shuicheng Yan, Si Liu‡.

Advances video reasoning through data-efficient reinforcement learning across eight video understanding tasks.
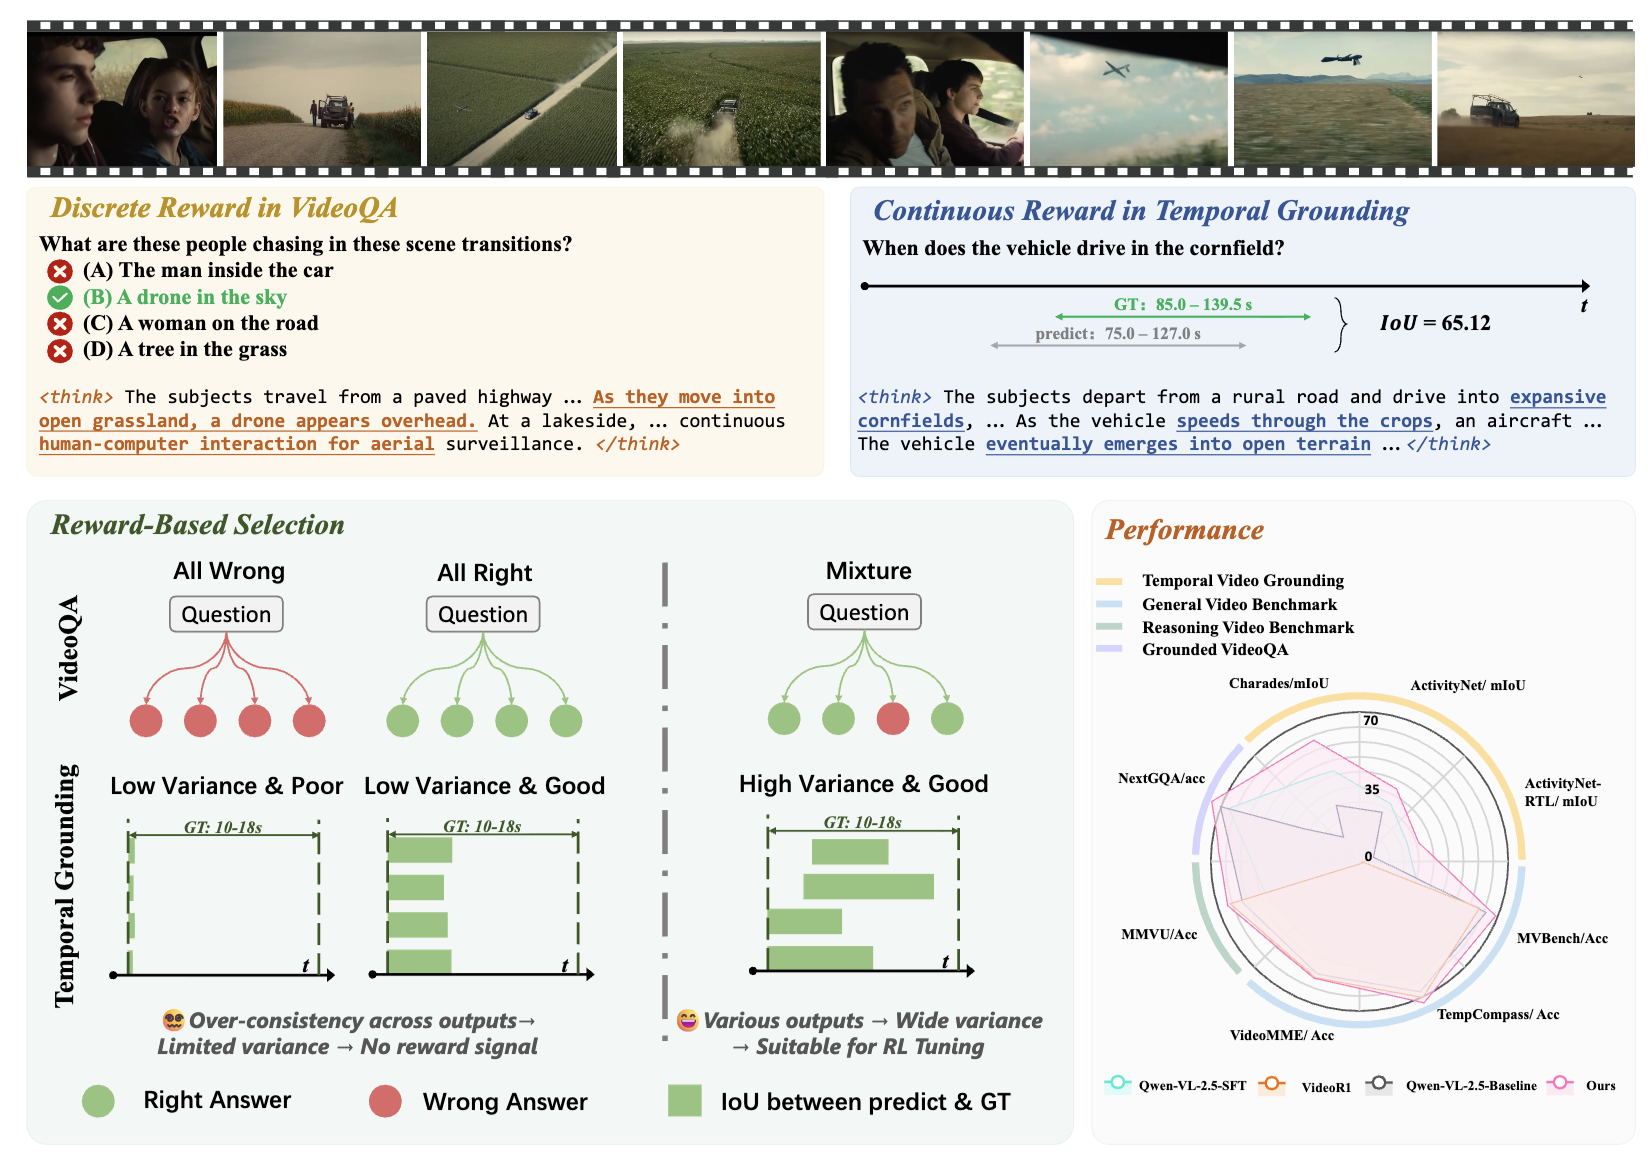
[PDF] [Code]
Show FigureHide Figure: Reinforcement Learning Tuning for VideoLLMs: Reward Design and Data Efficiency
Overview of Reinforcement Learning Tuning for VideoLLMs: Reward Design and Data Efficiency
Reinforcement Learning Tuning for VideoLLMs: Reward Design and Data Efficiency

CVPR 2025 LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding

Hongyu Li*, Jinyu Chen*, Ziyu Wei*, Shaofei Huang, Tianrui Hui, Jialin Gao, Xiaoming Wei, Si Liu.

Unifies fine-grained spatial and temporal localization for multimodal video understanding.
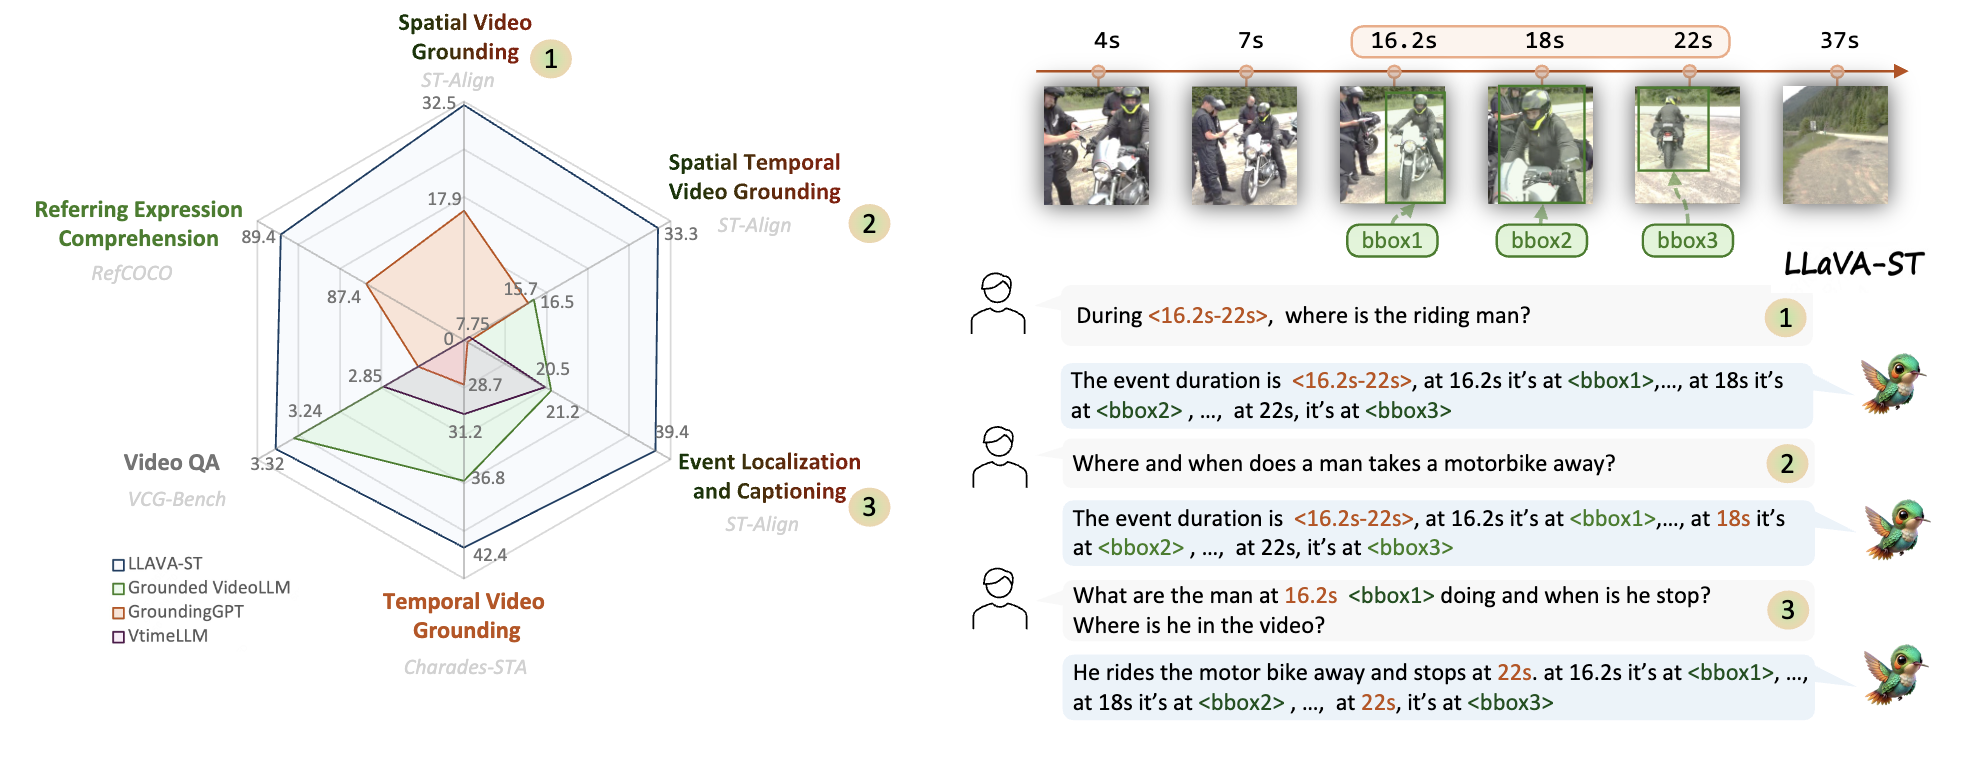
[PDF] [Code]
Show FigureHide Figure: LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding
Overview of LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding
LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding

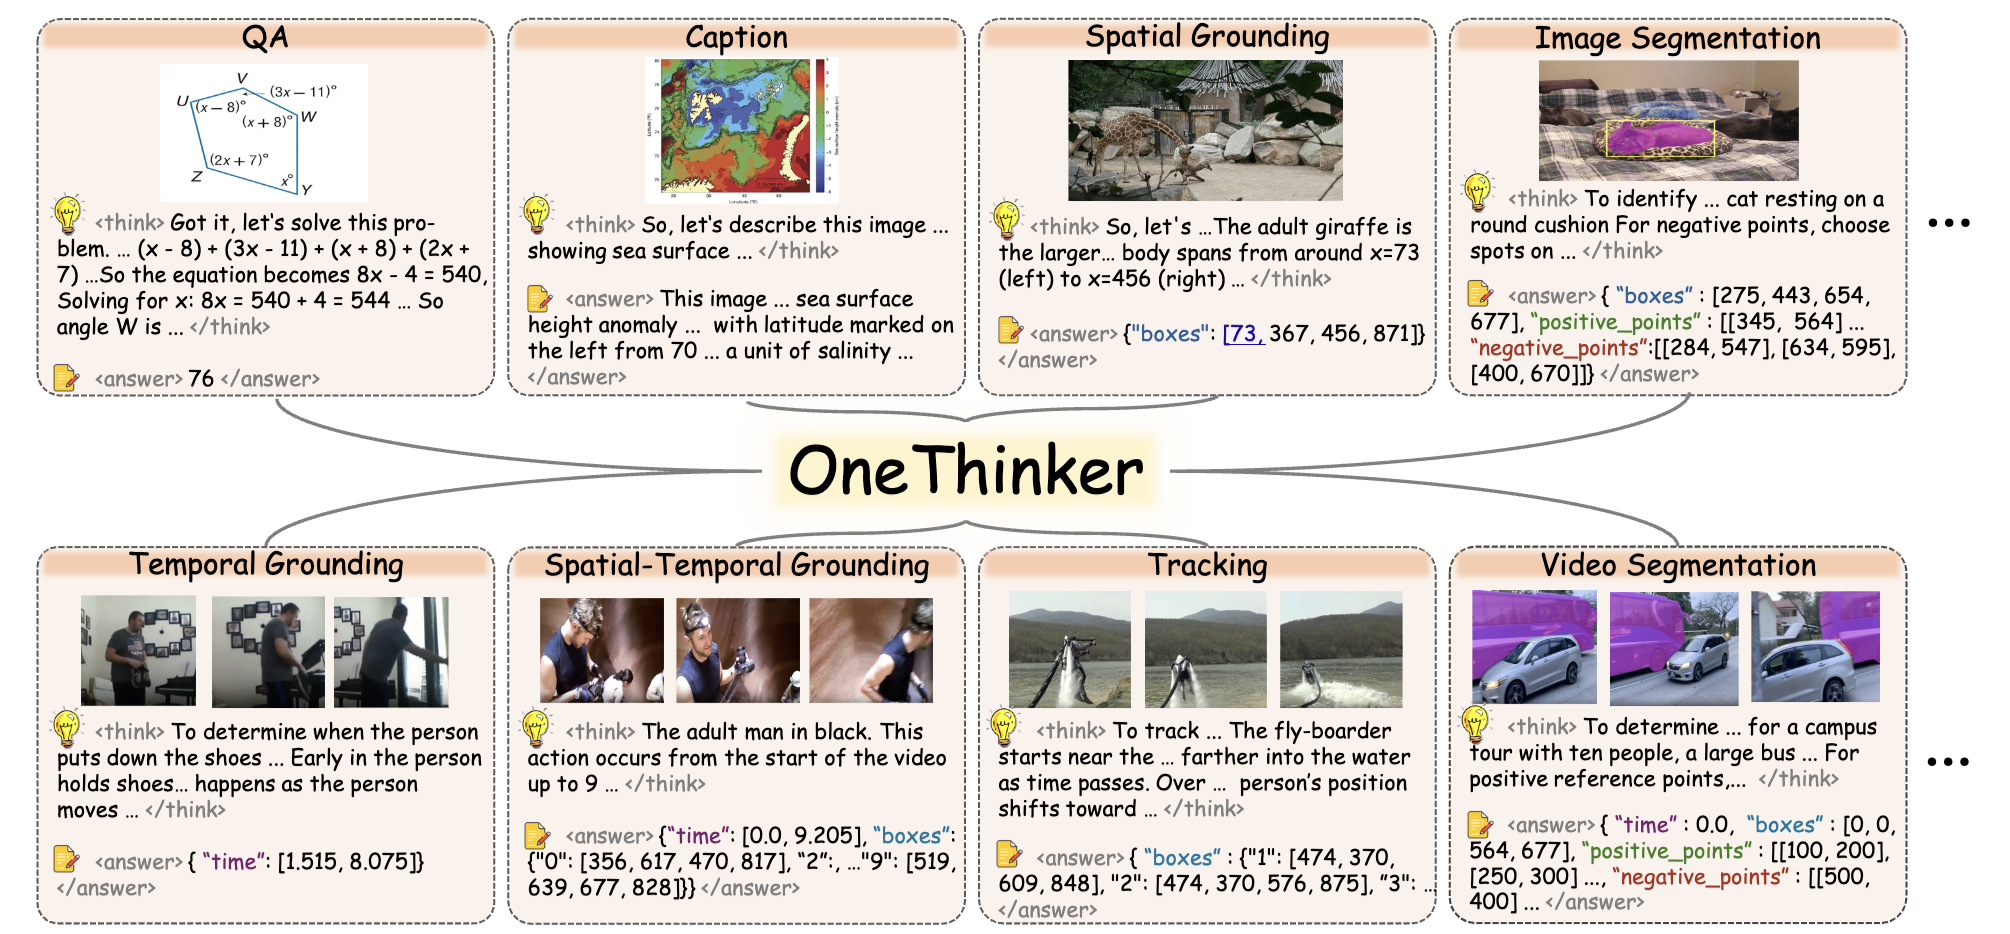
CVPR 2026 OneThinker: All-in-one Reasoning Model for Image and Video

Kaituo Feng, Manyuan Zhang, Hongyu Li, Kaixuan Fan, Shuang Chen, Yilei Jiang, Dian Zheng, Peiwen Sun, Yiyuan Zhang, Haoze Sun, Yan Feng, Peng Pei, Xunliang Cai, Xiangyu Yue.

One reasoning model for ten image and video tasks, evaluated on 31 benchmarks.
[PDF] [Code]
Show FigureHide Figure: OneThinker: All-in-one Reasoning Model for Image and Video
Overview of OneThinker: All-in-one Reasoning Model for Image and Video
OneThinker: All-in-one Reasoning Model for Image and Video

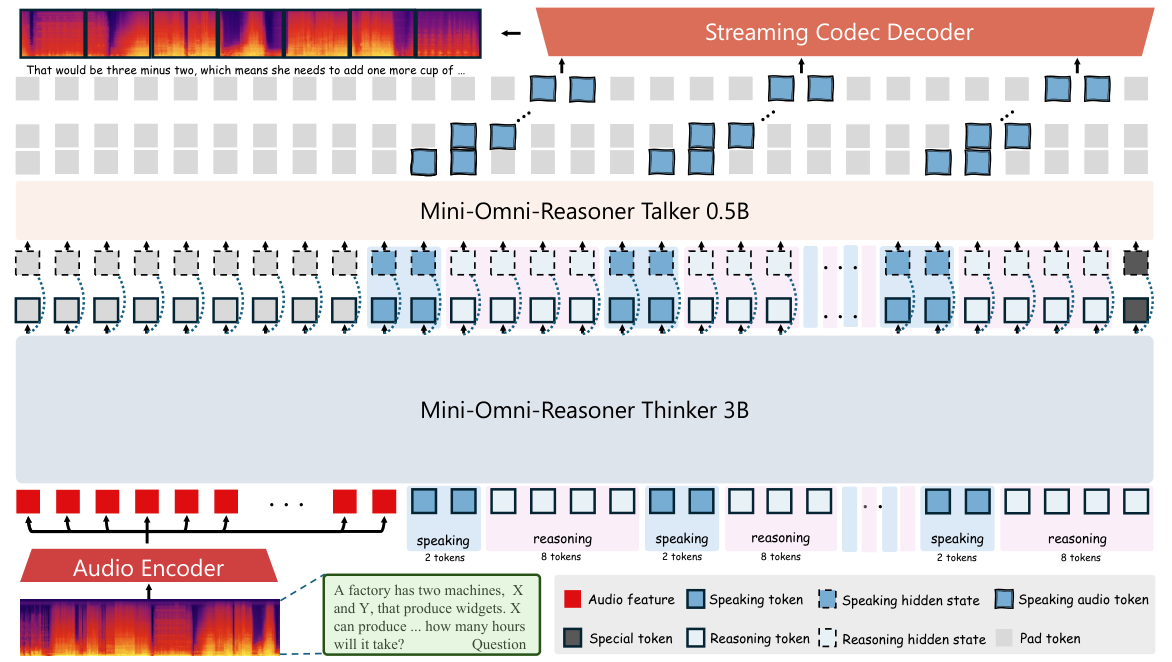
Tech Report Mini-Omni-Reasoner: Token-Level Thinking-in-Speaking in Large Speech Models

Zhifei Xie, Ziyang Ma, Zihang Liu, Kaiyu Pang, Hongyu Li, Jialin Zhang, Yue Liao, Deheng Ye, Chunyan Miao, Shuicheng Yan.

Enables speech models to reason while speaking, combining internal reasoning with continuous speech generation.
[PDF] [Code]
Show FigureHide Figure: Mini-Omni-Reasoner: Token-Level Thinking-in-Speaking in Large Speech Models
Overview of Mini-Omni-Reasoner: Token-Level Thinking-in-Speaking in Large Speech Models
Mini-Omni-Reasoner: Token-Level Thinking-in-Speaking in Large Speech Models

Visual Generation & Editing

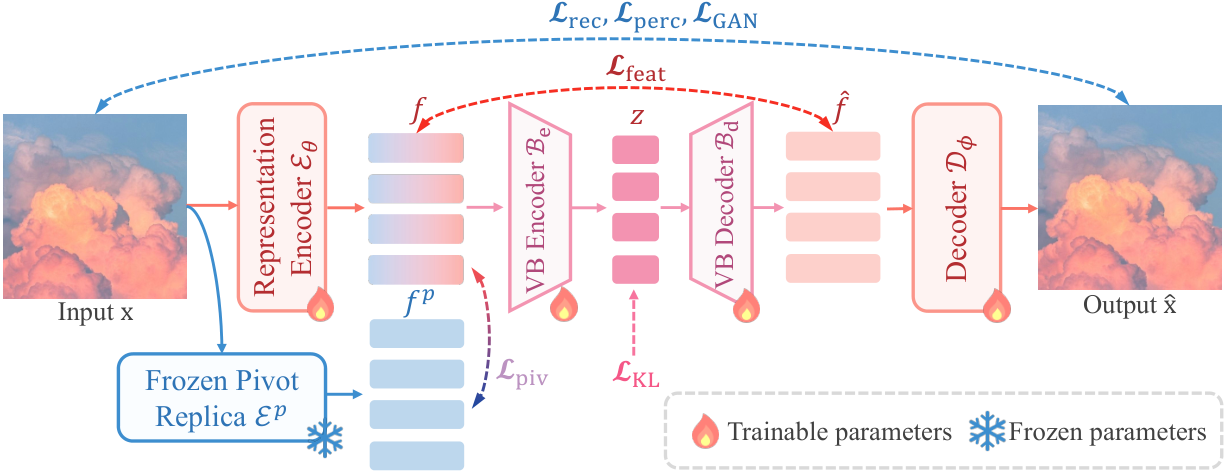
arXiv 2026 RPiAE: A Representation-Pivoted Autoencoder Enhancing Both Image Generation and Editing

Yue Gong*, Hongyu Li*, Shanyuan Liu*, Bo Cheng, Yuhang Ma, Liebucha Wu, Xiaoyu Wu, Manyuan Zhang, Dawei Leng‡, Yuhui Yin, Lijun Zhang‡.

A visual tokenizer that strengthens both image generation and editing while preserving reconstruction fidelity.
[PDF] [Code] [Project]
Show FigureHide Figure: RPiAE: A Representation-Pivoted Autoencoder Enhancing Both Image Generation and Editing
Overview of RPiAE: A Representation-Pivoted Autoencoder Enhancing Both Image Generation and Editing
RPiAE: A Representation-Pivoted Autoencoder Enhancing Both Image Generation and Editing

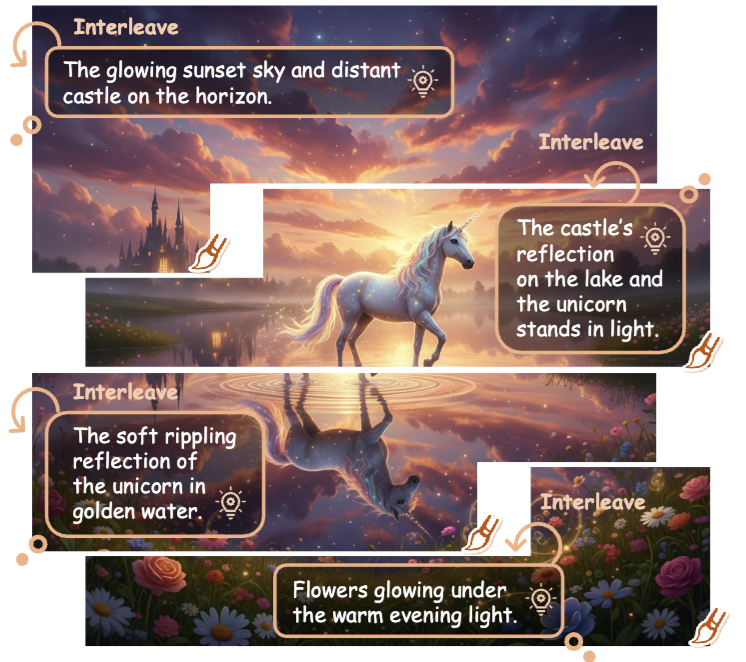
CVPR 2026 Thinking-while-Generating: Interleaving Textual Reasoning throughout Visual Generation

Ziyu Guo*, Renrui Zhang*†, Hongyu Li*, Manyuan Zhang†, Xinyan Chen, Sifan Wang, Yan Feng, Peng Pei, Pheng-Ann Heng.

First framework to interleave textual reasoning throughout image generation.
[PDF] [Code] [Project]
Show FigureHide Figure: Thinking-while-Generating: Interleaving Textual Reasoning throughout Visual Generation
Overview of Thinking-while-Generating: Interleaving Textual Reasoning throughout Visual Generation
Thinking-while-Generating: Interleaving Textual Reasoning throughout Visual Generation

ACM MM 2026 · Oral OmniAlpha: Aligning Transparency-Aware Generation via Multi-Task Unified Reinforcement Learning

Hao Yu*, Jinglin Wang*, Jiabo Zhan*, Rui Chen, Zile Wang, Huaisong Zhang, Hongyu Li, Xinrui Chen, Yongxian Wei, Chun Yuan.

Unifies transparency-aware image generation and editing through reinforcement learning across multiple RGBA tasks.
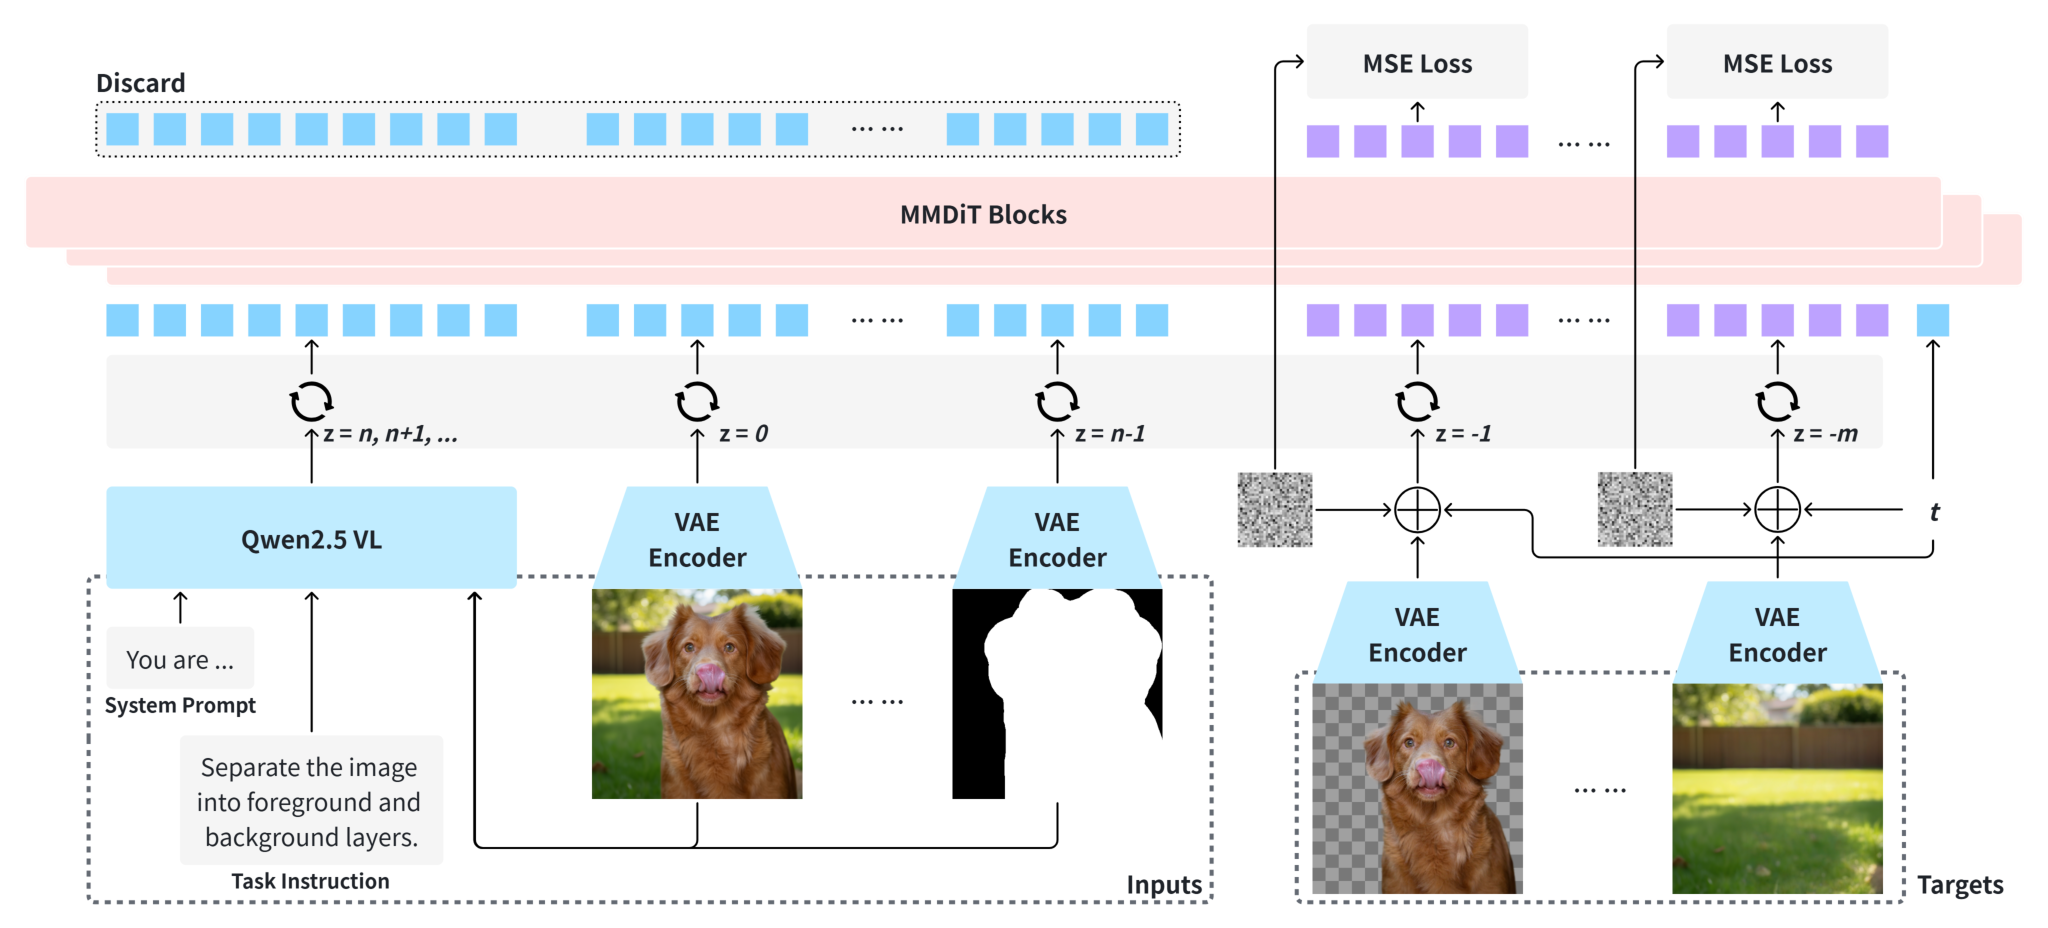
[PDF] [Code]
Show FigureHide Figure: OmniAlpha: Aligning Transparency-Aware Generation via Multi-Task Unified Reinforcement Learning
Overview of OmniAlpha: Aligning Transparency-Aware Generation via Multi-Task Unified Reinforcement Learning
OmniAlpha: Aligning Transparency-Aware Generation via Multi-Task Unified Reinforcement Learning

ECCV 2026 OpenSubject: Leveraging Video-Derived Identity and Diversity Priors for Subject-driven Image Generation and Manipulation

Yexin Liu, Manyuan Zhang, Yueze Wang, Hongyu Li, Dian Zheng, Weiming Zhang, Changsheng Lu, Harry Yang.

Scales identity-consistent image generation and editing with 2.5 million training samples mined from videos.
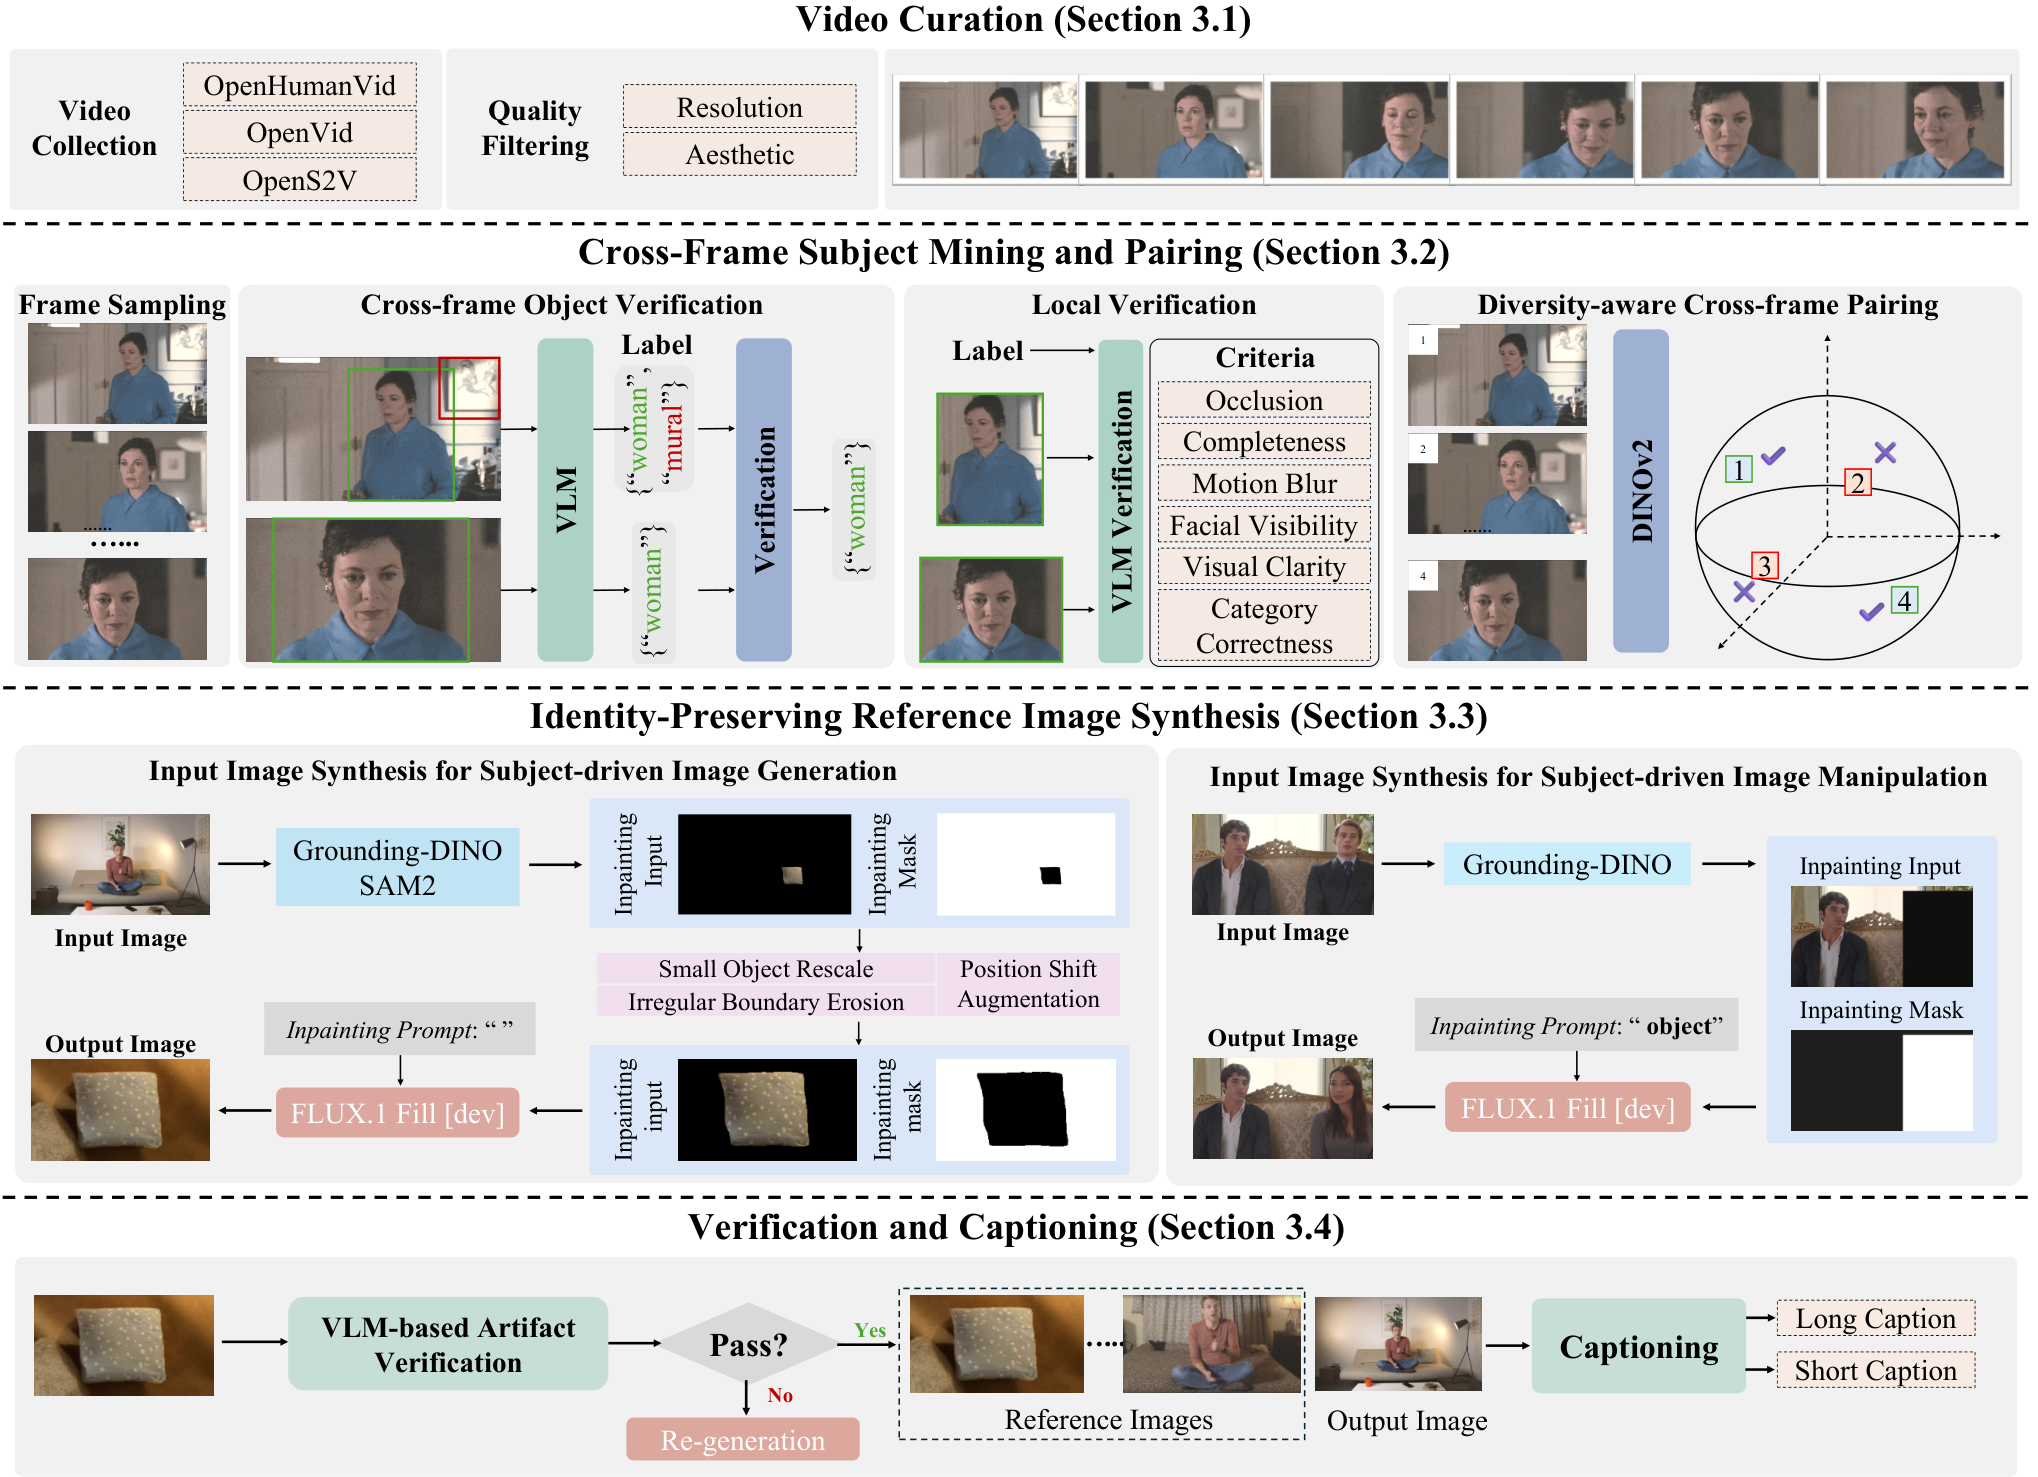
[PDF] [Code]
Show FigureHide Figure: OpenSubject: Leveraging Video-Derived Identity and Diversity Priors for Subject-driven Image Generation and Manipulation
Overview of OpenSubject: Leveraging Video-Derived Identity and Diversity Priors for Subject-driven Image Generation and Manipulation
OpenSubject: Leveraging Video-Derived Identity and Diversity Priors for Subject-driven Image Generation and Manipulation

arXiv 2026 Uni-Edit: Intelligent Editing Is A General Task For Unified Model Tuning

Dian Zheng, Manyuan Zhang, Hongyu Li, Hongbo Liu, Kai Zou, Kaituo Feng, Hongsheng Li.

Establishes intelligent editing as a single training task that improves understanding, generation, and editing together.
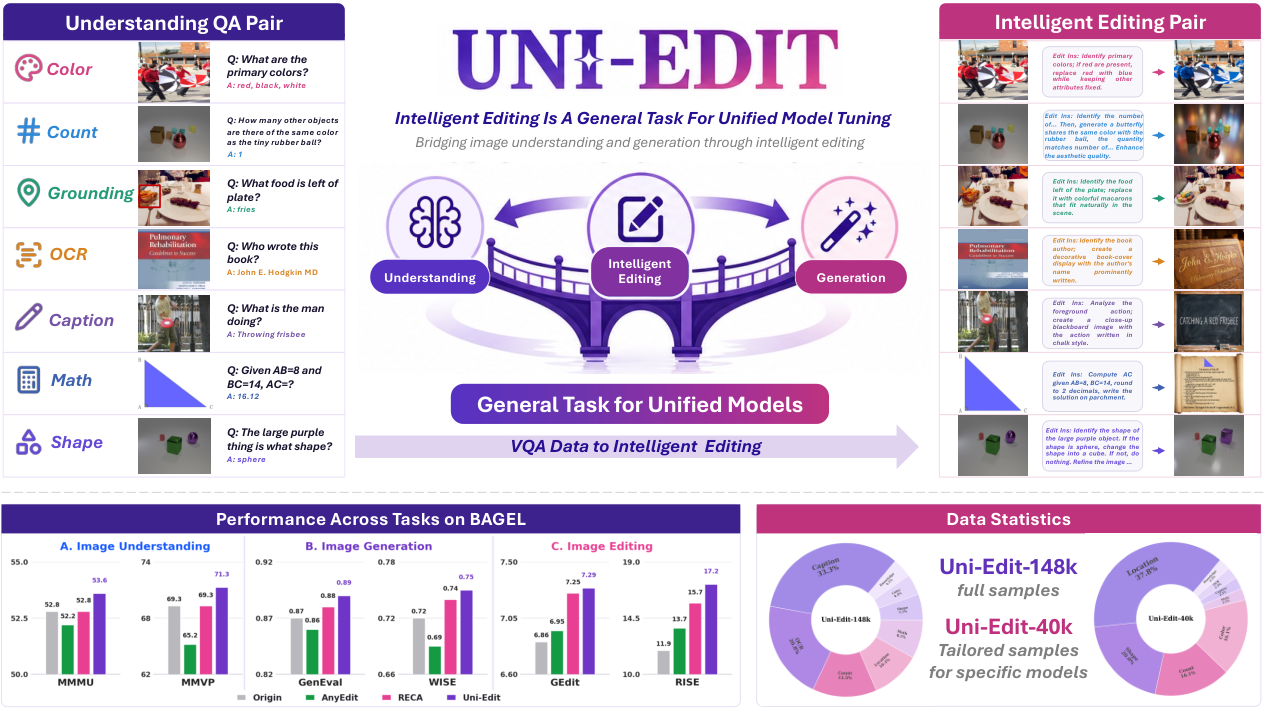
[PDF] [Code] [Project]
Show FigureHide Figure: Uni-Edit: Intelligent Editing Is A General Task For Unified Model Tuning
Overview of Uni-Edit: Intelligent Editing Is A General Task For Unified Model Tuning
Uni-Edit: Intelligent Editing Is A General Task For Unified Model Tuning

arXiv 2025 AIA: Rethinking Architecture Decoupling Strategy In Unified Multimodal Model

Dian Zheng, Manyuan Zhang, Hongyu Li, Kai Zou, Hongbo Liu, Ziyu Guo, Kaituo Feng, Yexin Liu, Ying Luo, Hongsheng Li.

Shows that aligning cross-modal attention improves understanding and generation without decoupling the model architecture.
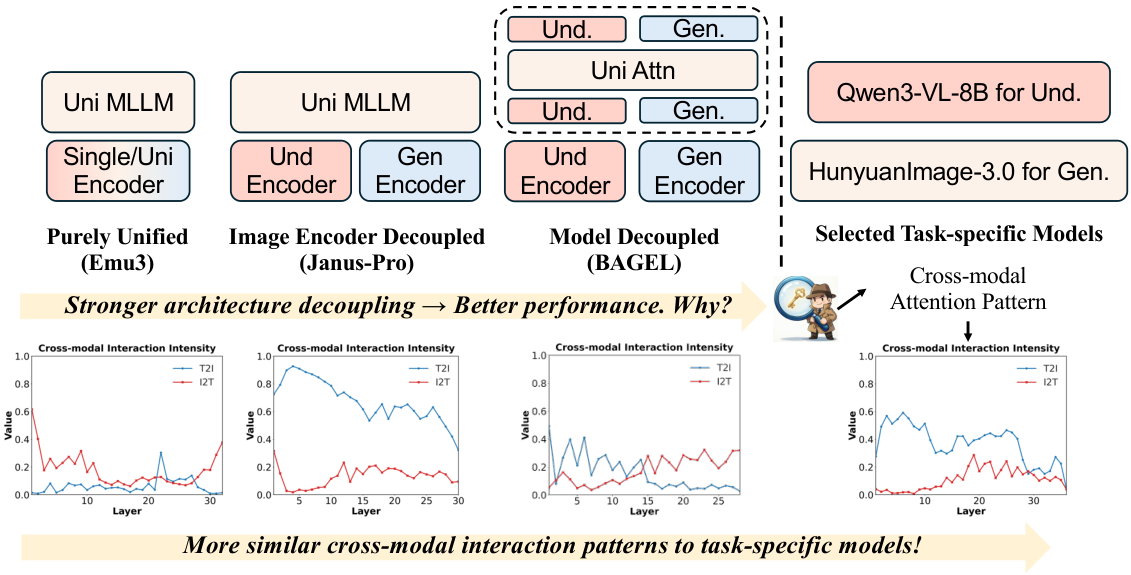
[PDF] [Code] [Project]
Show FigureHide Figure: AIA: Rethinking Architecture Decoupling Strategy In Unified Multimodal Model
Overview of AIA: Rethinking Architecture Decoupling Strategy In Unified Multimodal Model
AIA: Rethinking Architecture Decoupling Strategy In Unified Multimodal Model

Embodied AI

AAAI 2026 AerialVLA: A Vision-Language-Action Model for Aerial Navigation with Online Dialogue

Jinyu Chen*, Hongyu Li*, Zongheng Tang, Xiaoduo Li, Wenjun Wu, Si Liu.

An aerial navigation model that proactively asks questions to resolve uncertainty and reach its destination.
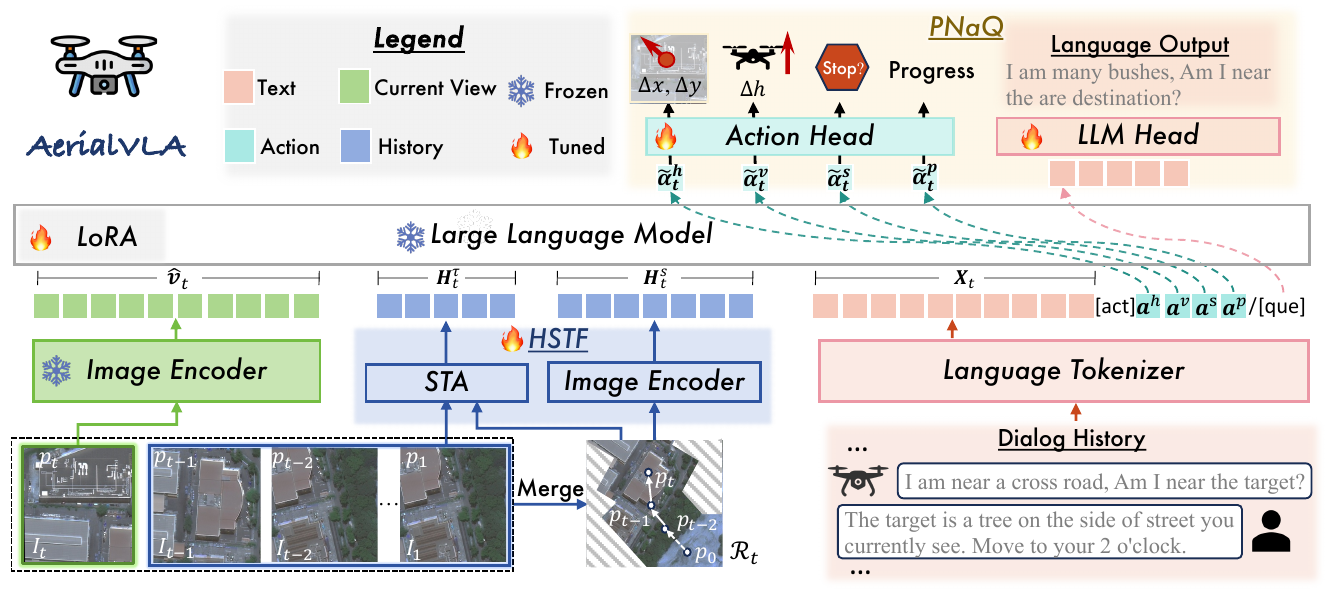
[PDF] [Code]
Show FigureHide Figure: AerialVLA: A Vision-Language-Action Model for Aerial Navigation with Online Dialogue
Overview of AerialVLA: A Vision-Language-Action Model for Aerial Navigation with Online Dialogue
AerialVLA: A Vision-Language-Action Model for Aerial Navigation with Online Dialogue

CVPR 2026 Parse, Search, and Confirmation: Training-Free Aerial Vision-and-Dialog Navigation with Chain-of-Thought Reasoning and Structured Spatial Memory
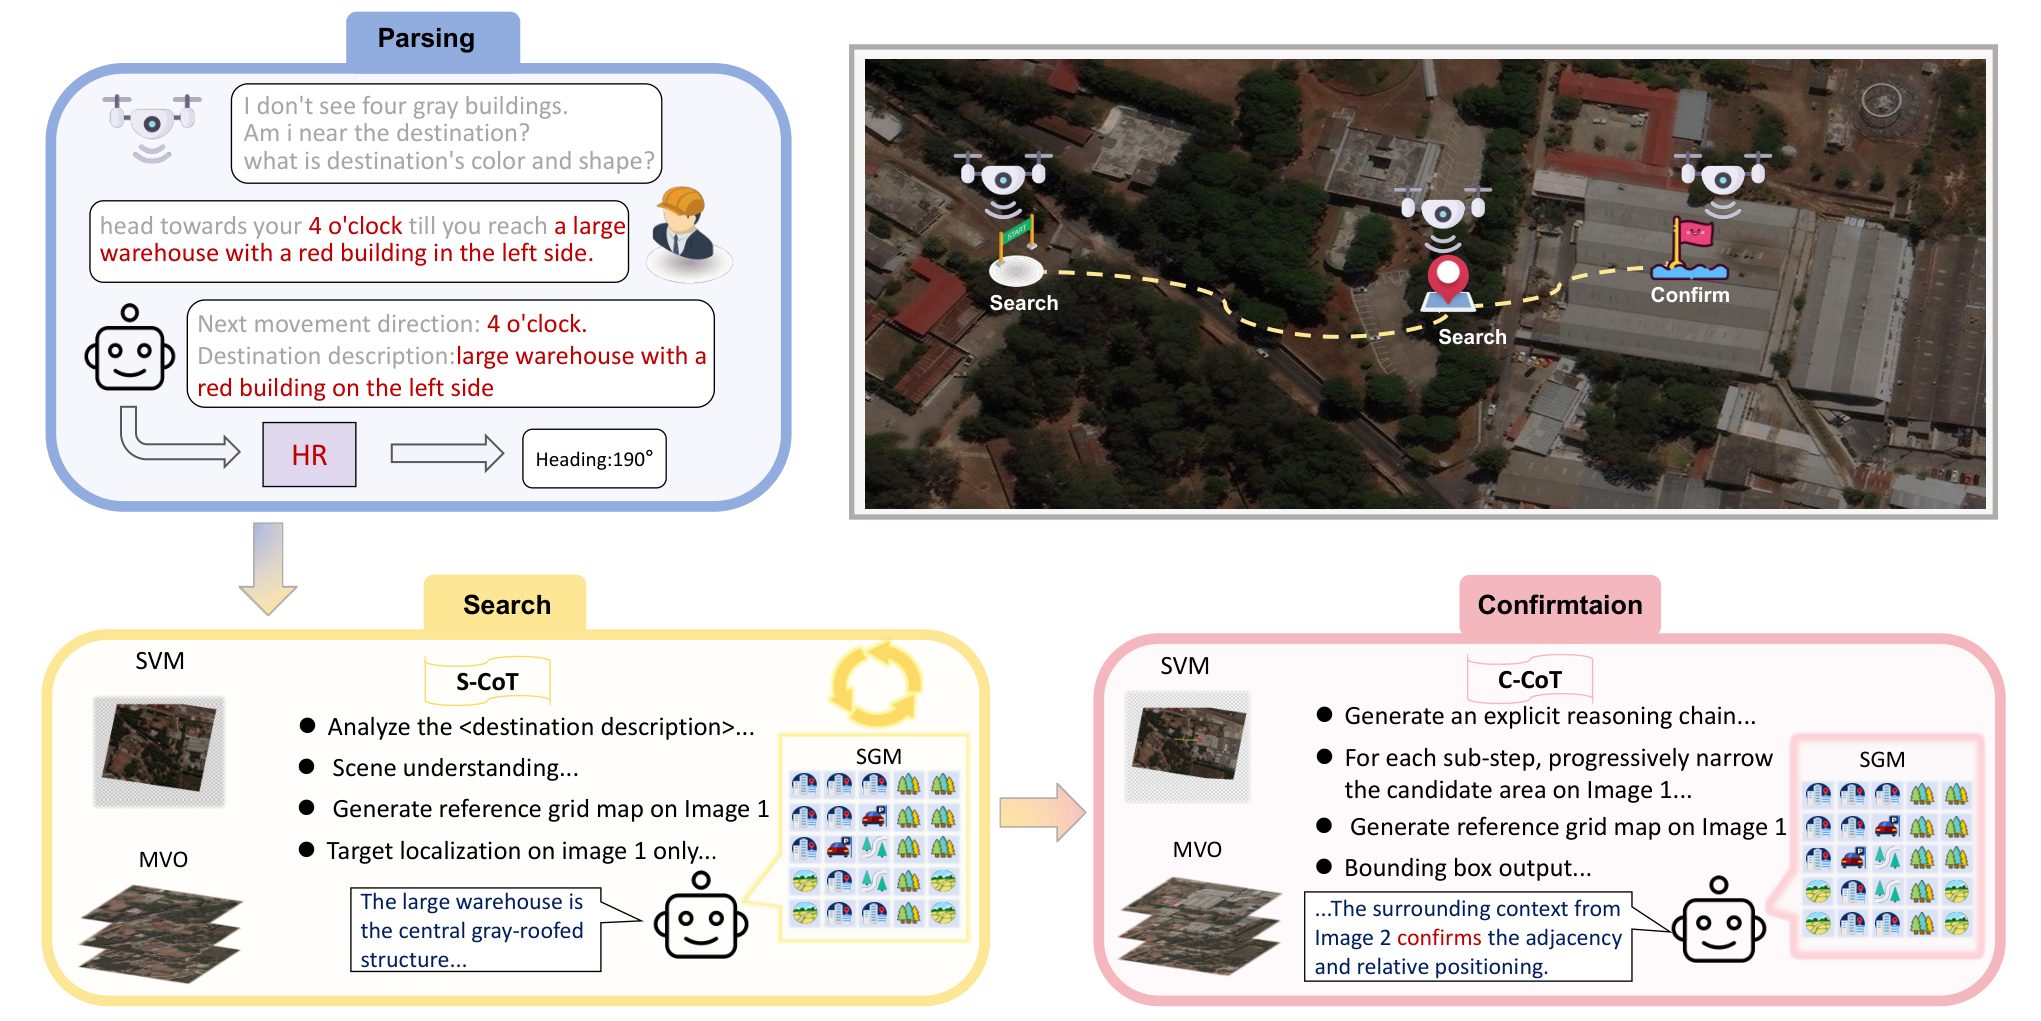
Yu Qi, Hongyu Li, Shaofei Huang, Tianrui Hui, Yaxiong Wang, Lechao Cheng, Zhun Zhong, Si Liu, Meng Wang.

Training-free aerial navigation that matches or outperforms several fine-tuned methods through reasoning and spatial memory.

[PDF] [Code]
Show FigureHide Figure: Parse, Search, and Confirmation: Training-Free Aerial Vision-and-Dialog Navigation with Chain-of-Thought Reasoning and Structured Spatial Memory
Overview of Parse, Search, and Confirmation: Training-Free Aerial Vision-and-Dialog Navigation with Chain-of-Thought Reasoning and Structured Spatial Memory
Parse, Search, and Confirmation: Training-Free Aerial Vision-and-Dialog Navigation with Chain-of-Thought Reasoning and Structured Spatial Memory

arXiv 2026 From Instruction to Event: Sound-Triggered Mobile Manipulation
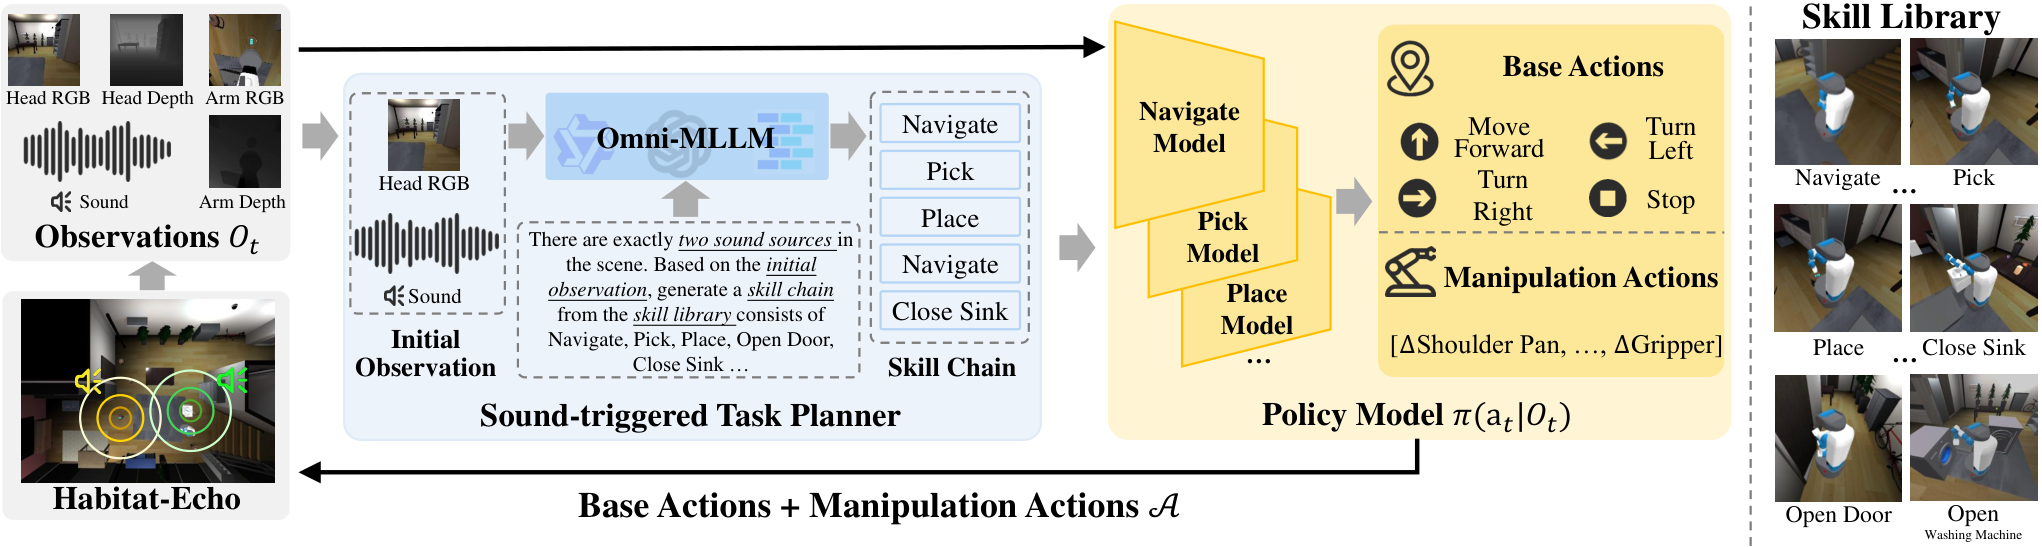
Hao Ju, Shaofei Huang, Hongyu Li, Zihan Ding, Si Liu, Meng Wang, Zhedong Zheng.

Moves mobile manipulation beyond explicit instructions, enabling robots to act on environmental sound events.

[PDF]
Show FigureHide Figure: From Instruction to Event: Sound-Triggered Mobile Manipulation
Overview of From Instruction to Event: Sound-Triggered Mobile Manipulation
From Instruction to Event: Sound-Triggered Mobile Manipulation

ICLR 2025 Point Cluster: A Compact Message Unit for Communication-Efficient Collaborative Perception

Zihan Ding, Jiahui Fu, Si Liu‡, Hongyu Li, Siheng Chen, Hongsheng Li, Shifeng Zhang, Xu Zhou.

Compact point clusters reduce communication costs while preserving the geometry and semantics needed for collaborative perception.

[PDF]
Show FigureHide Figure: Point Cluster: A Compact Message Unit for Communication-Efficient Collaborative Perception
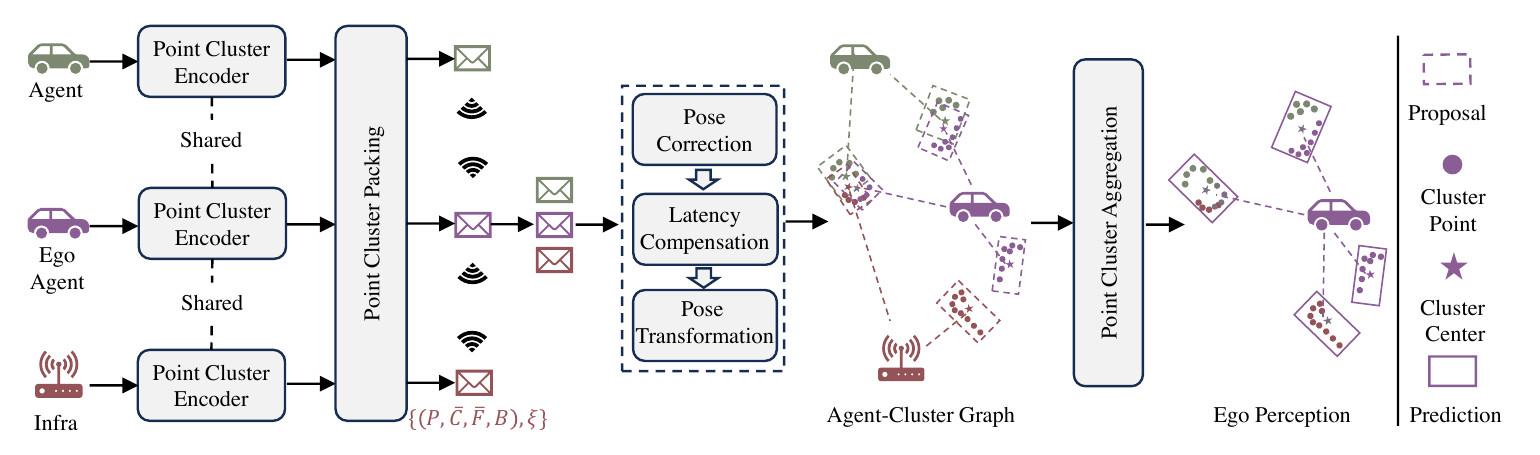
Overview of Point Cluster: A Compact Message Unit for Communication-Efficient Collaborative Perception
Point Cluster: A Compact Message Unit for Communication-Efficient Collaborative Perception

Visual Segmentation & Grounding

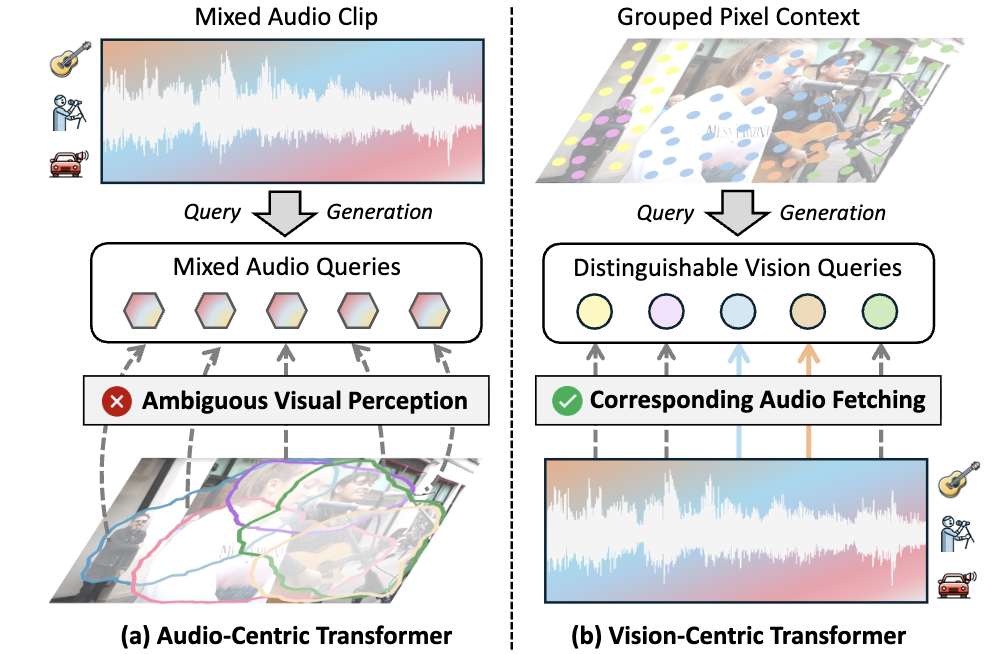
CVPR 2025 Revisiting Audio-Visual Segmentation with Vision-Centric Transformer

Shaofei Huang, Rui Ling, Tianrui Hui, Hongyu Li, Xu Zhou, Shifeng Zhang, Si Liu, Richang Hong, Meng Wang.

Vision-centric audio-visual segmentation that separates sounding objects in mixed audio while preserving precise object boundaries.
[PDF] [Code]
Show FigureHide Figure: Revisiting Audio-Visual Segmentation with Vision-Centric Transformer
Overview of Revisiting Audio-Visual Segmentation with Vision-Centric Transformer
Revisiting Audio-Visual Segmentation with Vision-Centric Transformer

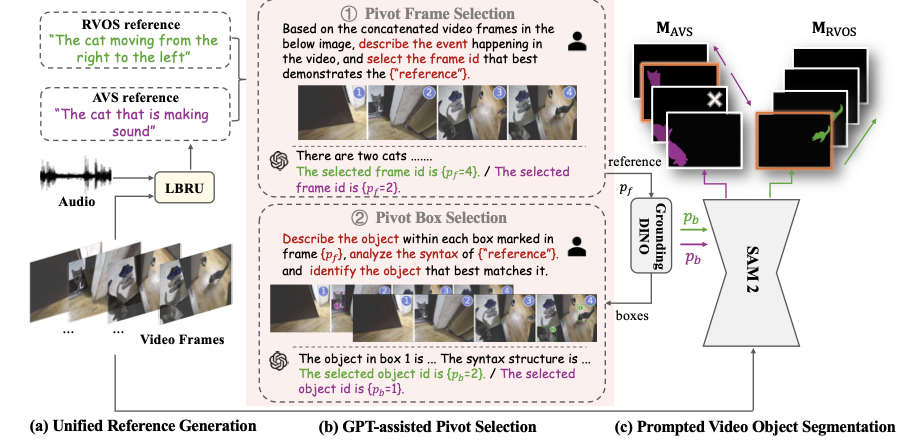
AAAI 2025 Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation

Shaofei Huang*, Rui Ling*, Hongyu Li*, Tianrui Hui, Zongheng Tang, Xiaoming Wei, Jizhong Han, Si Liu.

Training-free video segmentation guided by audio or language, with performance competitive with fully supervised methods.
[PDF] [Code]
Show FigureHide Figure: Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation
Overview of Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation
Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation

ACM MM 2024 Dynamic Prompting of Frozen Text-to-Image Diffusion Models for Panoptic Narrative Grounding

Hongyu Li*, Tianrui Hui*, Zihan Ding, Jing Zhang, Bin Ma, Xiaoming Wei, Jizhong Han, Si Liu‡.

Repurposes frozen text-to-image diffusion models for precise narrative grounding through dynamically adapted language prompts.

[PDF]
Show FigureHide Figure: Dynamic Prompting of Frozen Text-to-Image Diffusion Models for Panoptic Narrative Grounding
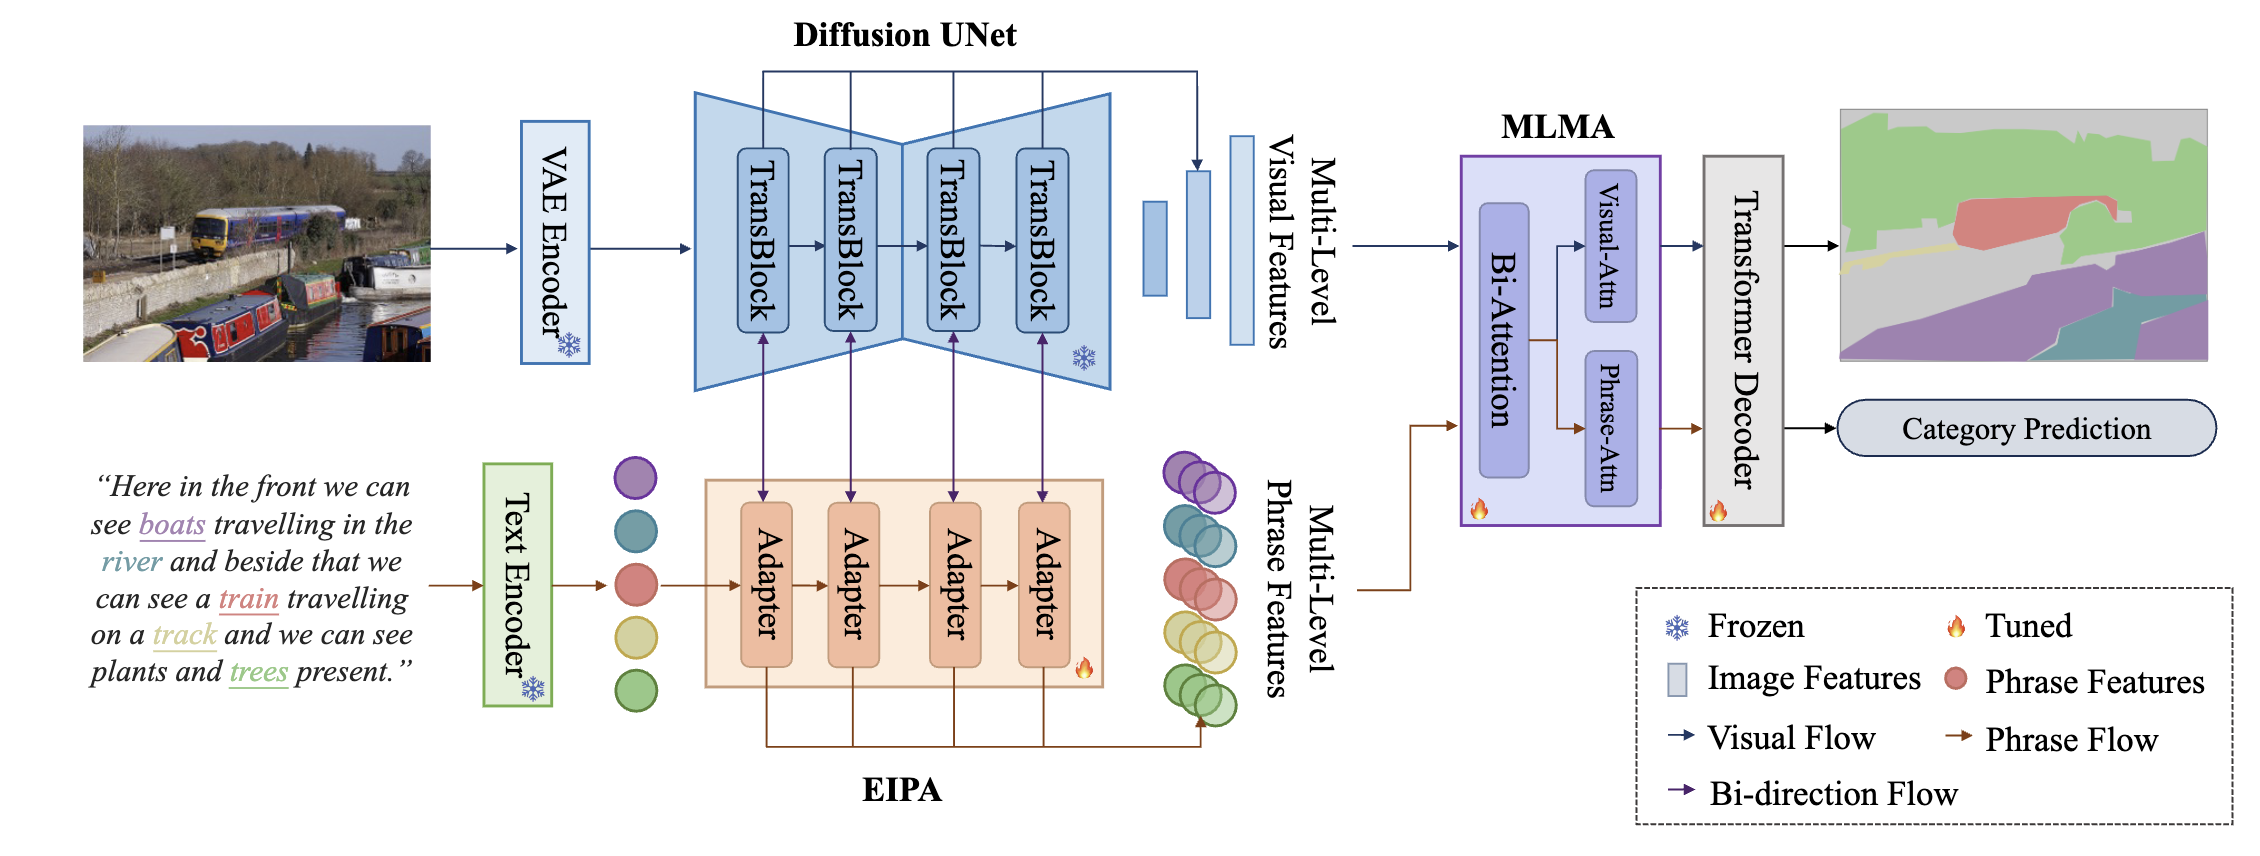
Overview of Dynamic Prompting of Frozen Text-to-Image Diffusion Models for Panoptic Narrative Grounding
Dynamic Prompting of Frozen Text-to-Image Diffusion Models for Panoptic Narrative Grounding

📖 Education

  • Sep 2024 – Present, Master’s student, School of Artificial Intelligence, Beihang University.
  • Sep 2019 – Jul 2024, Bachelor of Software Engineering, Beihang University.

📄 Academic Service

Conference reviewer: AAAI 2026, CVPR 2026, ICLR 2026, ICML 2026.